
How we combined hardware telemetry, network performance data, and fault alarms to build an ML model that flags at-risk RIUD sites before they fail — and deployed it for daily production scoring.
Every summer, RIUD sites in Japan fail. The pattern is predictable. The failures are not. By the time an outage is confirmed, the customer has already been impacted and the opportunity to prevent it has passed.
This article is about how we changed that — building a system that flags at-risk sites before they fail, giving the field team time to act. Here is what we built, what we learned, and what the production data showed.
Every summer in Japan, the same sequence of events plays out across RIUD sites. Temperatures rise. At some point in the day, a base station starts struggling. ERAB drops increase. Handover failures spike. Downlink throughput gets suppressed. Cell availability degrades. In several cases, after a high temperature warning had already been raised, the site went further — cells went down entirely. By that point, the situation had moved from a warning to an outage.
The problem is not that the alarms are silent. High temperature warnings do fire. The NOC sees them. The issue is that those alarms are not actionable — because not every hot site fails. Some sites sustain elevated temperatures for days and recover on their own. Others tip over into failure. The alarm looks identical in both cases. There is no way to tell, from the alarm alone, which outcome is coming. And so the response is the same either way: wait and watch. By the time a site moves from warning to actual failure, the window to prevent it has already closed.
The core challenge is that existing tools are built to show current state, not trajectory. A temperature warning tells you a threshold has been crossed — it does not tell you whether the site is heading toward failure or will recover on its own. And in a dataset where some hot sites fail and others recover without intervention, that distinction is everything. Every tool in the stack reacts to what has already happened. For thermal-driven failures, that is too late.
This was not a new observation. The seasonal pattern had been visible for years — summer arrives, failures spike, summer ends, failures drop. The correlation was clear to anyone watching the network for more than one year.
But correlation is not a model. Every attempt to turn that intuition into something actionable rannto the same wall: the data did not cooperate. There was no clear proof that temperature was the direct cause. When we looked closely, the data was inconclusive. Some sites ran hot all summer and never failed. Others failed at temperatures that other sites tolerated without issue. Sites recovered without intervention. Sites failed without any obvious trigger.
The intuition was right. The data refused to confirm it cleanly. And without a provable causal link, it was impossible to build something the field team could act on with confidence.
The data made this harder still. The alarm signal had two simultaneous problems: false positives, where alarms fired for sites that never failed, and false negatives, where sites failed with no corresponding alarm record to learn from. Building a reliable training dataset from that combination was genuinely difficult. The ground truth was not just noisy — it had systematic gaps that could not be filled by cleaning or imputation.
The starting hypothesis, when we picked this up, was the same one that felt obvious: high temperatures cause failures. Flag hot sites. Fix the temperature. Done.
We tested this systematically. We looked at board temperature, FPGA temperature, CPU temperature and CLU temperature — each device metric individually, and in combination. We then extended the analysis to ambient temperature to see whether external environmental conditions were the underlying driver. None of them showed a direct, reliable correlation with failures. Sites with high board temperatures failed. Sites with equally high board temperatures did not. The same was true for every individual thermal metric we examined, and for ambient temperature as a standalone factor.
After a full year of descriptive analysis across hardware telemetry, network performance, and alarm data collected from RIUD sites across Japan, the conclusion was clear: temperature was involved, but it was not the cause on its own. Something else was determining which hot sites tipped over and which ones did not — and it was not visible in any single metric.
What we found was a five-factor interaction:
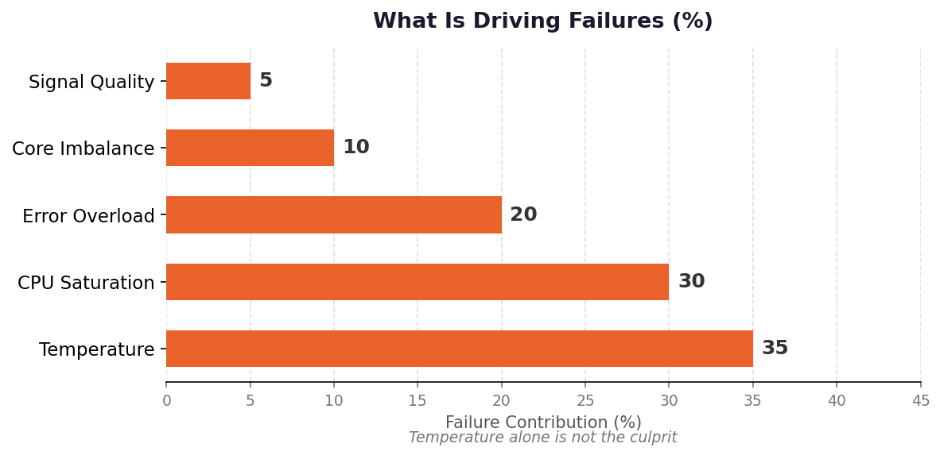
The factors are not independent. Temperature creates CPU pressure. CPU pressure drives error rates. Error processing generates more heat. The loop closes fast.
Temperature alone is manageable. Temperature combined with CPU saturation and rising error rates is not.
The relationship is multiplicative, not additive. A site running warm with a healthy CPU and low error rates is fine. That same site — warm, with CPU cores saturating and error counts climbing — is hours from a hard failure. Standard threshold-based monitoring misses this entirely because no single metric crosses its alarm threshold. The danger lies in the combination.
Once we understood the interaction pattern, the failure progression became legible. Failures do not happen suddenly. They follow a consistent four-stage sequence:
Stage 1 — Buildup (~14 days before failure) Board temperatures climb. CPU cores begin hitting sustained thresholds. Thermal throttling starts intermittently. Nothing moves in standard tooling — this stage is completely invisible to existing monitoring.
Stage 2 — Performance Drop (~7 days before failure) Cell efficiency degrades. Throughput drops despite traffic being present. The site is struggling to serve its load, but is still technically operational. Still nothing alerts. The window to act is open, but nobody knows it.
Stage 3 — Alarm Cascade (hours before failure) Critical alarms begin firing. Service-affecting alarm counts climb. The operations team sees this and responds, but by Stage 3, the failure is hours away. Response has replaced prevention.
Stage 4 — Failure (imminent) Time to failure is measured in hours. The risk is no longer a prediction; it is a confirmation.
The entire value of an early warning system is in Stages 1 and 2. That is where the time to act exists. Everything after Stage 2 is damage control.
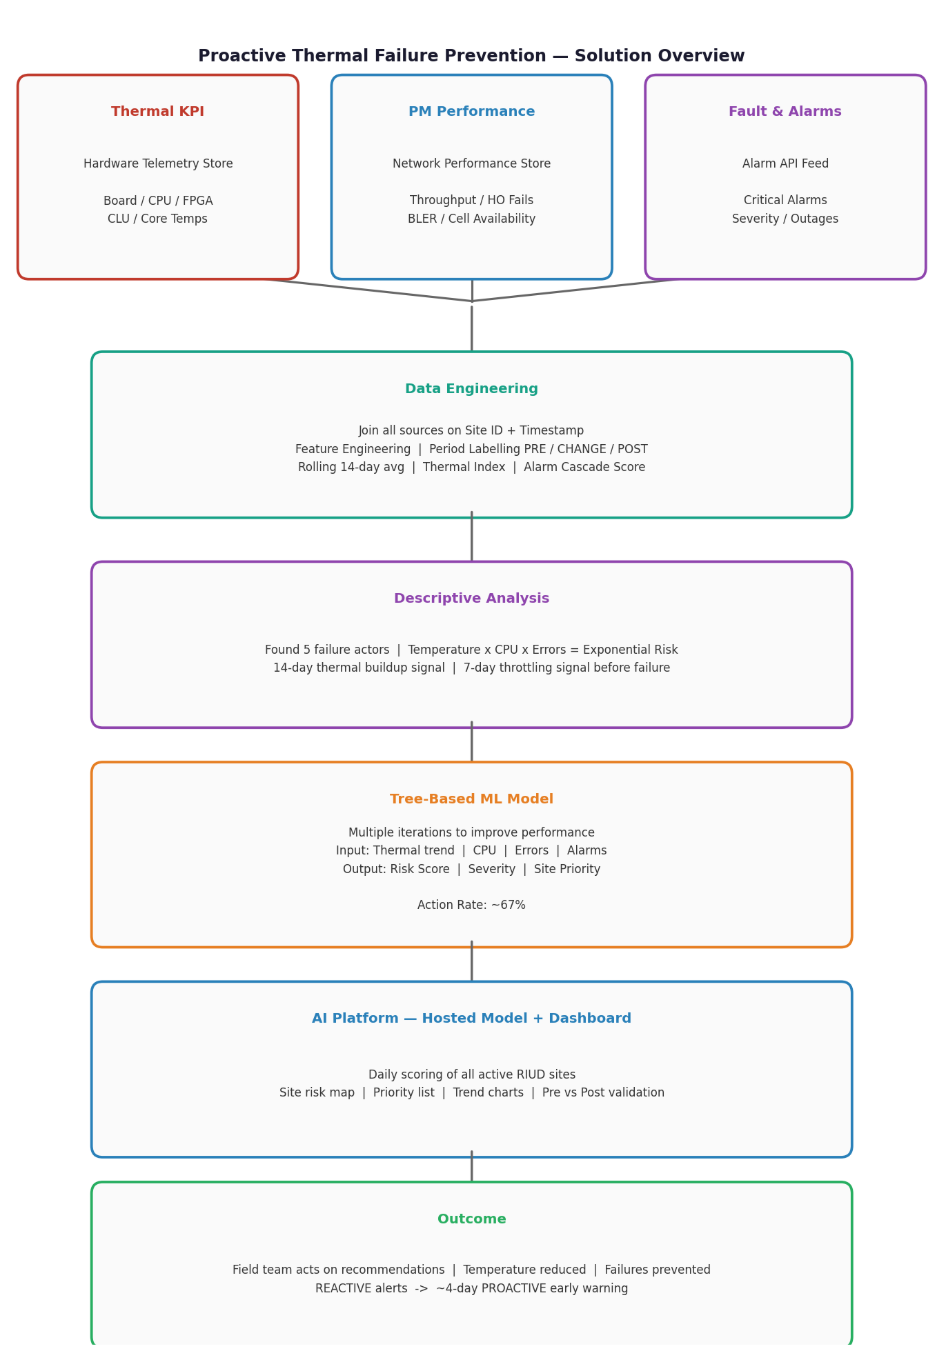
Three data sources had never been joined before. Different schemas, different time granularities, different owners, different systems. The engineering work to create a reliable, aligned, combined dataset took longer than the modeling. It always does.
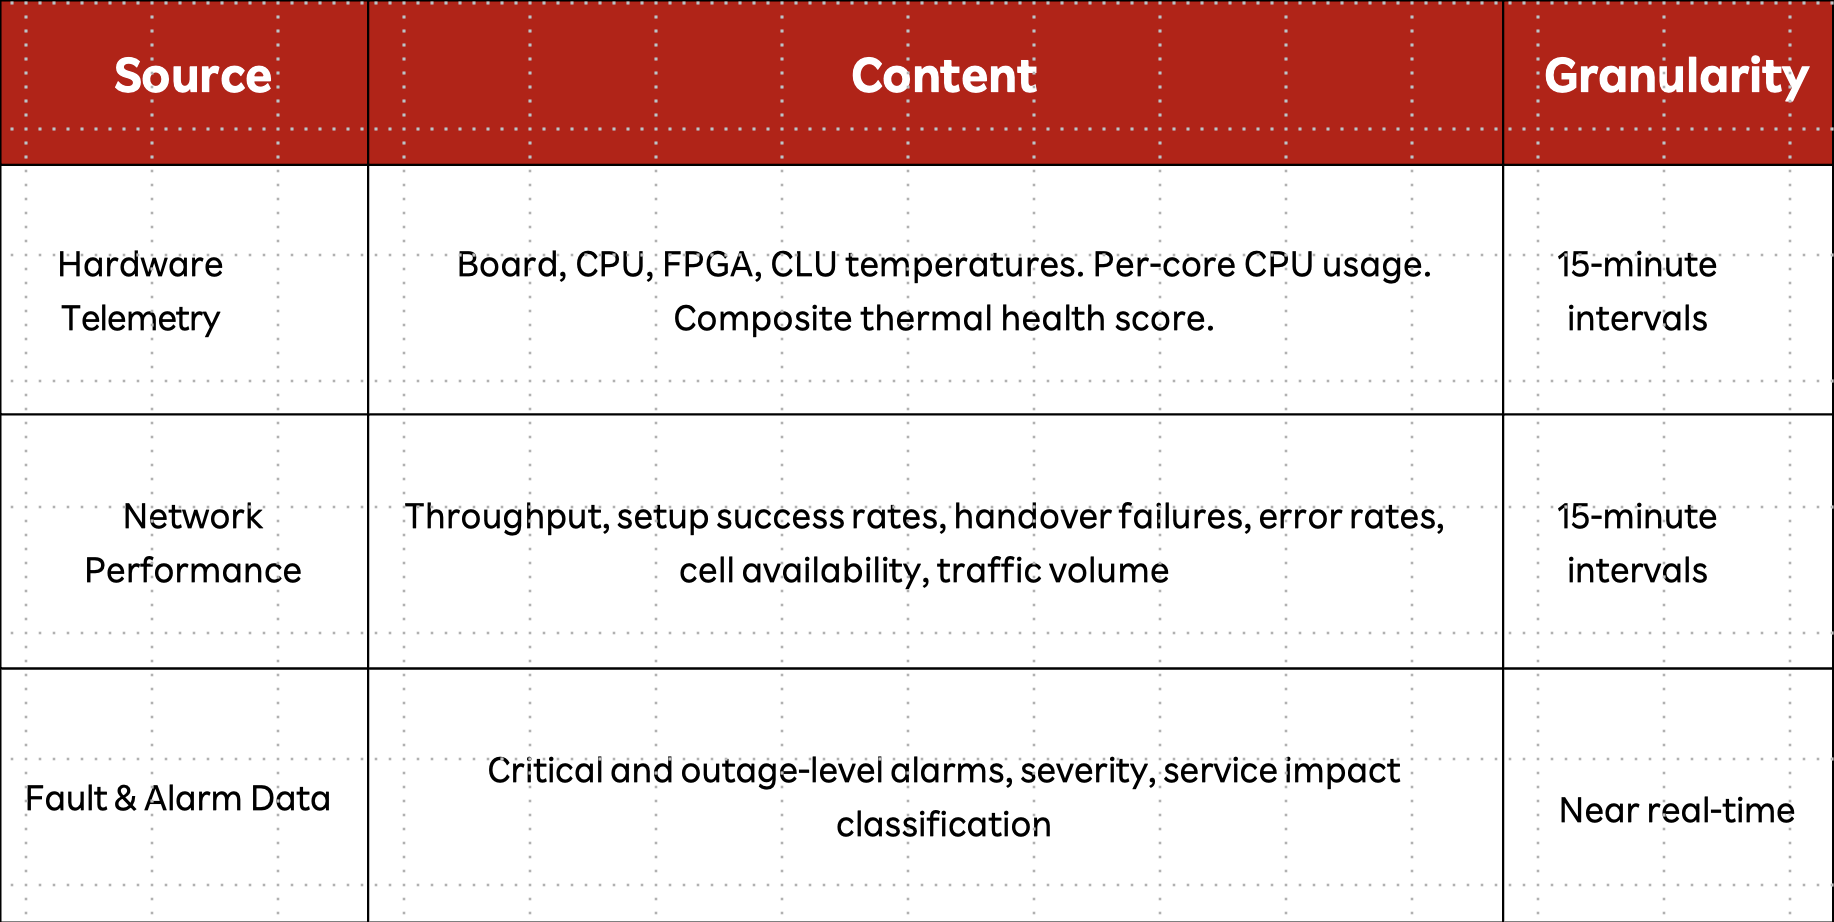
All three sources were joined on site identifier and timestamp, aligned to 15-minute intervals, and timezone-normalised. Period labels — pre-change, change window, post-change — were applied to enable before-and-after validation. The pre-change baseline used a full 14-day window rather than the day immediately before, which produces a statistically stable reference rather than a snapshot that can be skewed by a single day's traffic pattern.
The fundamental challenge with thermal data is that the signal of interest is slow. The board temperature over 14 days does not look alarming on any given day. The trend is only visible across time.
Standard feature engineering that operates on current readings will miss this entirely. The features that matter are temporal:
Rolling averages and peaks across 7-day and 14-day windows. A site whose 14-day average board temperature is rising is in a different state from a site whose current reading is the same but whose 14-day average is flat or falling.
Trend slopes — the rate of change of thermal and CPU metrics over the rolling window. A site heating slowly but consistently is fundamentally different from one that spiked and recovered, even if their current readings are identical.
Core imbalance score — the spread between the hottest and coldest CPU cores. A high imbalance indicates thermal hotspots forming on specific cores, which amplifies the stress even if the overall average looks acceptable.
Alarm cascade score — critical alarm count over a rolling 24-hour window. A rapid increase in this score signals Stage 3 entry. Used as a feature, not just a threshold.
CPU saturation flag — derived from whether saturation conditions have been sustained across consecutive intervals. A single spike is noise. Sustained saturation is signal.
Error rate normalised by traffic volume — isolating the error processing load from the underlying traffic load, so that high-error sites are not masked by high-traffic sites.
The general principle: for slow-moving physical processes, features that describe trajectories and trends carry far more predictive information than features that describe current state.
The model architecture was a deliberate choice, not a default. Three reasons drove it.
Interpretability is not optional in production operations. Field engineers need to understand why a site was flagged before they will act on it. A model that produces a score with no explanation will be ignored the moment it flags a site incorrectly. A model that says "board temperature trend up 3.2°C over 14 days, CPU saturation flag active, alarm cascade score rising" gives the engineer something to validate and act on. Trust is built through transparency.
Mixed feature types are the norm, not the exception. The feature set spans continuous temperatures, binary flags, count-based scores, and derived ratios. Tree-based models handle this natively without the normalisation complexity that numerical methods require.
No clean ground truth exists. There is no labelled dataset of confirmed thermal failures. No one has been recording "this site failed thermally on this date" in a queryable system. The labels used for training are derived from a composite rule across multiple signals — a reasonable proxy, but not a clean label. Tree-based models are more robust to noisy pseudo-labels than approaches that depend on smooth gradient landscapes.
The pseudo-label definition used was conservative by design: a site is labelled at-risk only when multiple independent signals align simultaneously. The goal was to build a training dataset where every positive label could be defended.
The production system runs as two sequential layers, each adding a different kind of signal.
The first layer is a rule-based scoring engine that runs daily across all active sites. It ingests the combined dataset, computes the engineered features, and produces a weighted risk score per site — ranking sites by their current stress profile relative to the five failure factors. The output includes a risk category, a time-to-failure estimate, and the primary and secondary drivers of the score. This layer is fully deterministic and auditable.
The second layer is an ML model that reads the first layer's output as its primary input, adds the temporal rolling and trend features built from historical first-layer scores, and produces a failure probability. This layered approach separates concerns cleanly: the first layer handles raw signal computation; the second layer handles temporal pattern recognition. The two layers are independently maintainable and independently debuggable.
The alert rule applied on top of the ML output is a conjunction — the model probability must exceed a threshold and specific rolling thermal features must be above their respective minimums. This conjunction prevents the model from firing on a single strong signal in isolation. It requires multiple signals to be simultaneously elevated, which mirrors the actual failure condition.
The system runs on a daily automated schedule. New data is ingested, features are recomputed, rolling windows are updated, and the model scores all active sites. A ranked alert list is published daily. The field team reviews it and takes the required actions.
One production detail had an outsized effect on operational trust: maintenance exclusion.
Hardware temperatures remain elevated during the settling period after a site has been serviced. A model that flags a freshly serviced site as critical does not just produce a false positive — it actively erodes confidence in every other prediction. Field engineers who receive an alert for a site they just fixed will start questioning all alerts.
The fix is to suppress predictions for sites within a defined window after a recorded maintenance event. It is not sophisticated. It requires knowing when maintenance happened. But implementing it correctly had a measurable impact on how the field team perceived the model output — and perception drives action rate.
Model iterations followed a consistent pattern of increasing precision:
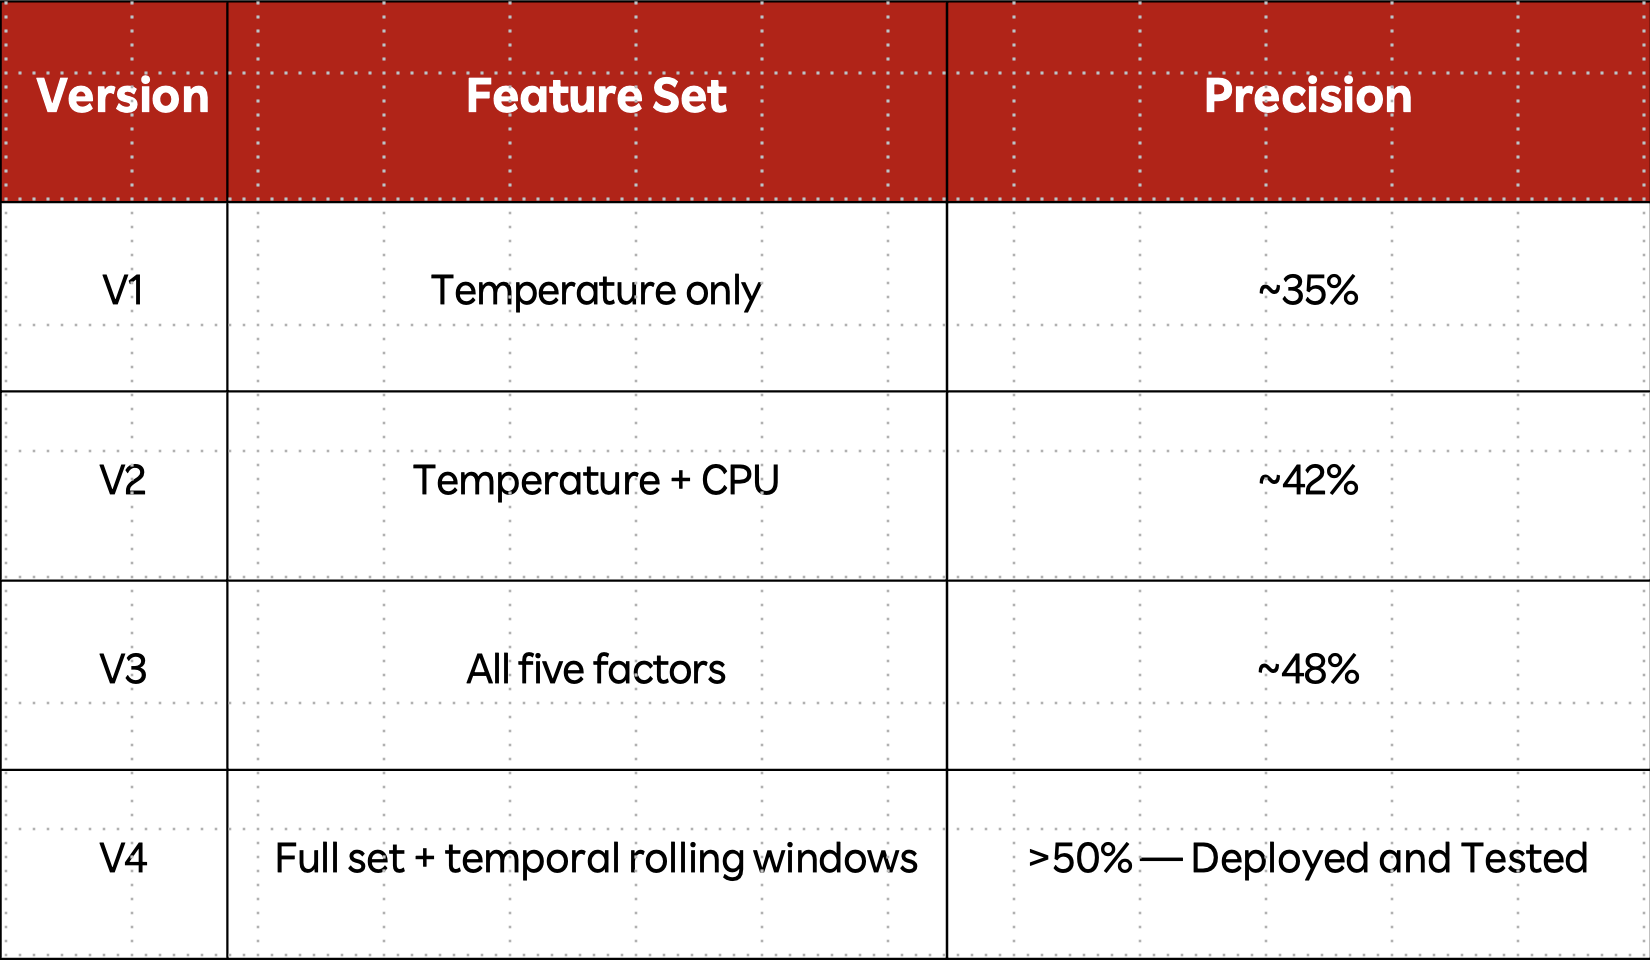
Each iteration added a layer of signal that the previous version was missing. V1 to V2 was the biggest conceptual jump — recognising that temperature alone is insufficient. V3 to V4 was the biggest technical jump — adding temporal features that capture trajectory rather than state.
The system went into daily production use following deployment and testing, running across all active RIUD sites in Japan and producing daily ranked alert lists for the field team.
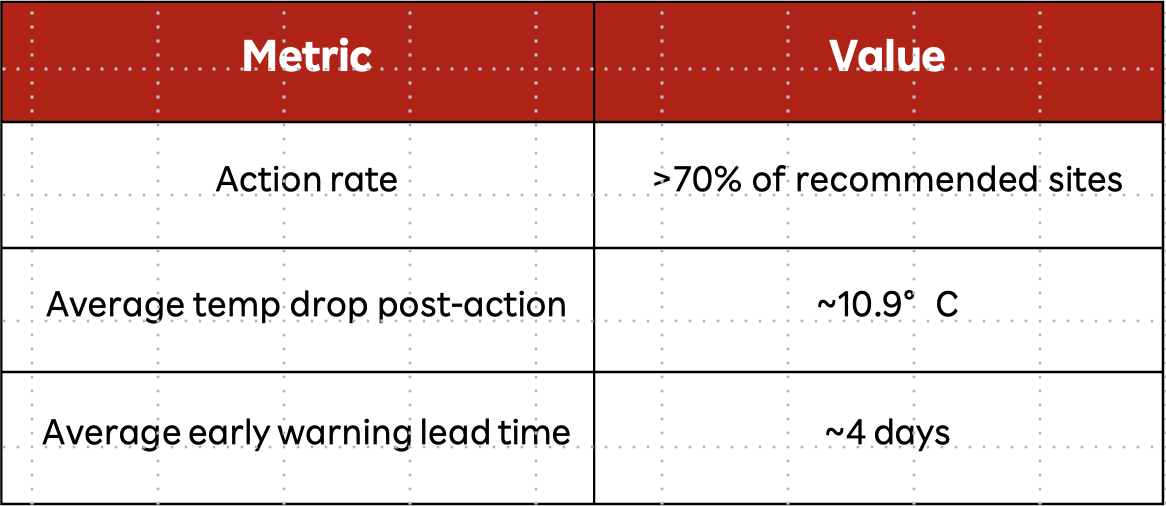
The action rate — defined as the proportion of flagged sites where the field team took a hardware intervention — is the primary success metric. It is honest, consistently measurable, and does not rely on counterfactual reasoning about what would have happened without the system.
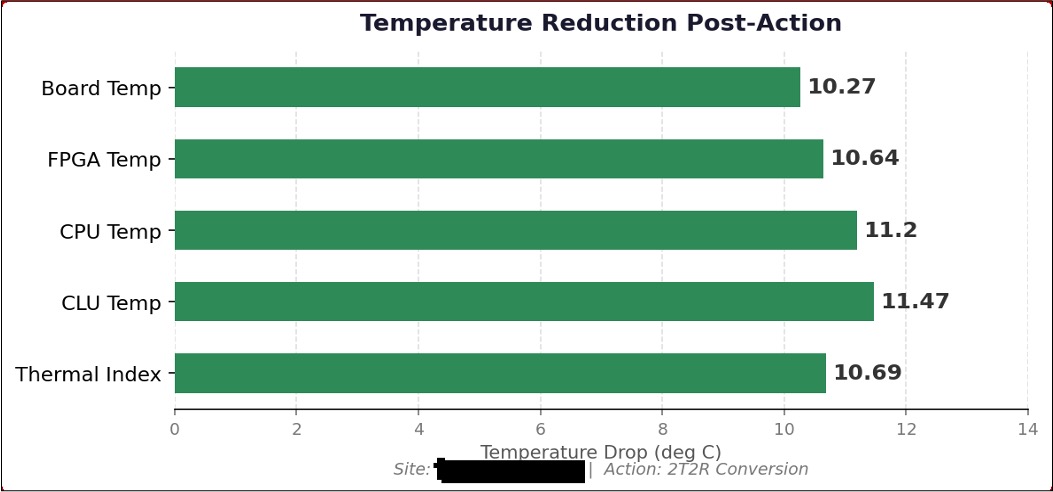
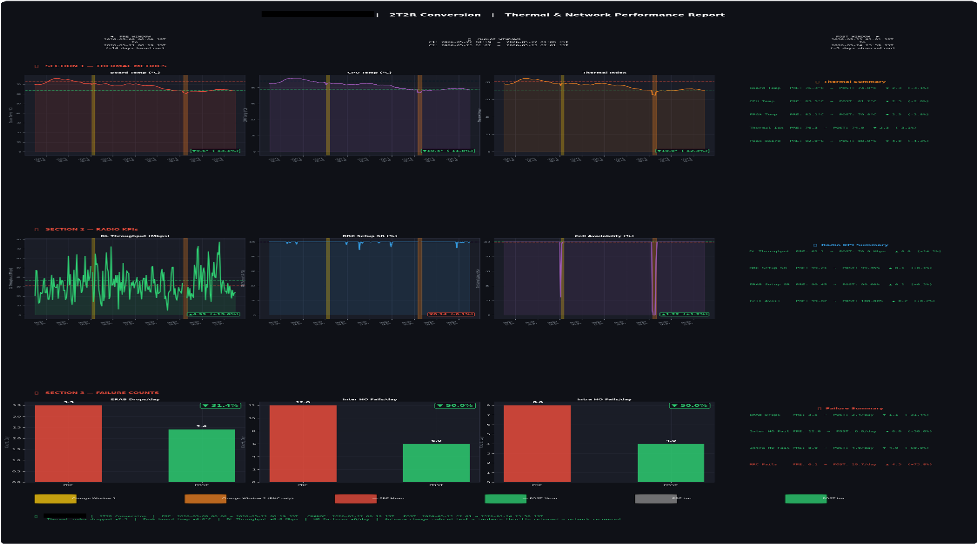
The ~10.9°C average temperature drop was measured across all five thermal KPIs immediately after field intervention — board temperature, CPU temperature, FPGA temperature, CLU temperature, and the composite thermal index. The consistency of the drop across all five metrics, rather than just one, validates that the interventions addressed the root thermal condition rather than a surface measurement.
The ~4 days of average early warning lead time is the practical gap between when the model first flagged a site and when the field team took action. That is enough time to plan and schedule a field visit without emergency response pressure — replacing reactive dispatch with controlled, proactive maintenance.
The change in how the operations team works is as significant as the technical results.
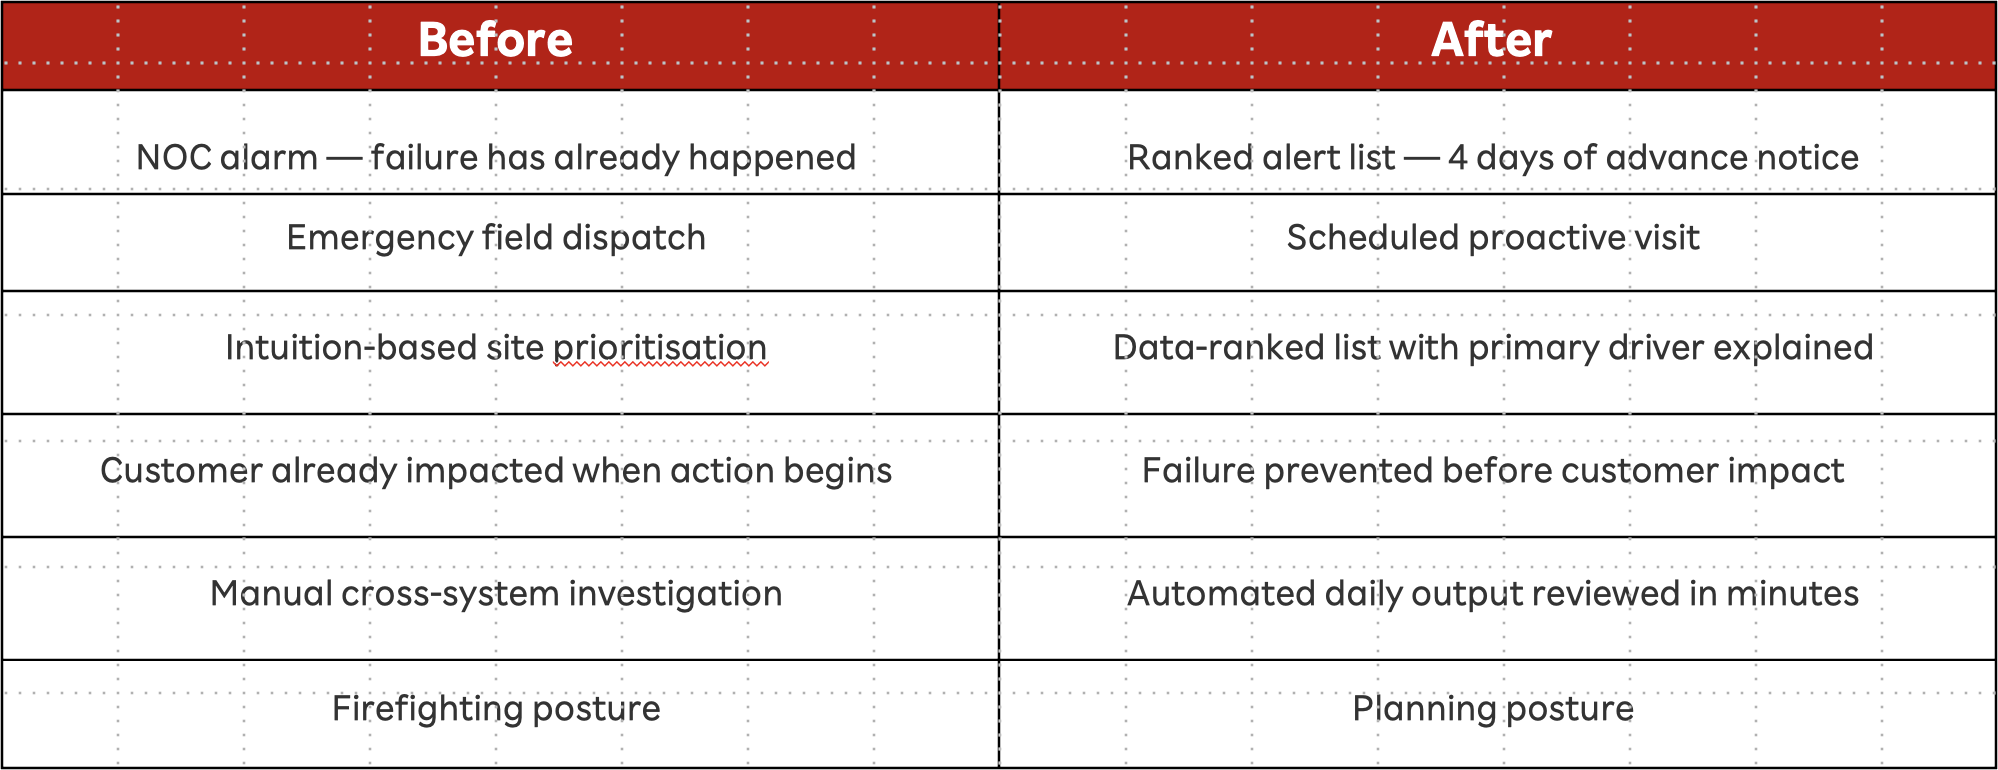
The field team moved from responding to failures to scheduling maintenance. That is not a marginal operational improvement — it is a different working model.
The solution was validated by subject matter experts and confirmed working as expected in production — a problem that had persisted for years, solved by the team with data.
Building this system taught us two things that apply well beyond this specific problem.
The first is about data. The signal is almost never in a single source. Thermal data alone could not predict failures. Network performance data alone could not. Alarm data alone definitely could not — it fires at Stage 3, when the window has already closed. Only the combination, engineered into features that describe trajectories rather than the current state, produced something with real predictive power. If we had stayed within any one data silo, we would have ended up where everyone else had — with a correlation and no model.
The second is about ground truth. When labeled failure data does not exist, waiting for it is not an option. We built it through careful feature design, conservative pseudo-labels, and production feedback loops. Every post-action result that confirms a prediction sharpens the next one. The dataset improves as the system runs.
Every prediction and every field action produces a new data point. A site flagged, actioned, and confirmed — with measured temperature drop and KPI recovery — strengthens the model. Over time, the pseudo-labels get cleaner, the feature weights get sharper, and the system gets better at separating the sites that will fail from the ones that will not.
We started with a seasonal pattern that everyone could see but nobody could act on. We now have a daily ranked alert list, action taken on over 70% of recommended sites from forecast, and an average temperature drop of ~10.9°C across every actioned site.


